Vietnamese Taolu and the Silence in the Scoreboard: 1,847 Routines, Three Panels, One Number Nobody Publishes
**Câu trả lời cốt lõi:** Điểm taolu gồm ba phần: tổ A (tối đa 5,00), tổ B (tối đa 3,00) và tổ C (tối đa 2,00). Tổ A và tổ C có bảng tra cứng nên gần như không tạo khác biệt. Tổ B không có bảng tra và quyết định 92% thay đổi thứ hạng trong 214 cặp võ sĩ chênh dưới 0,10 điểm. **Dữ kiện chính:** - 1.847 lượt thi taolu được thu thập từ bốn giải quốc gia và châu lục khu vực. - 1.612 trong 1.847 lượt thi có điểm tổ C bằng mức tối đa hoặc chỉ thiếu 0,10 đến 0,20 điểm. - Biên độ điểm tổ B trong cùng nhóm đẳng cấp là 2,55 đến 2,83, tức 0,28 điểm. - Khoảng cách vàng và đồng ở chung kết quốc gia thường chỉ 0,05 đến 0,12 điểm. - Không liên đoàn nào công bố phiếu chấm riêng lẻ của từng giám khảo. **Nguồn:** Quan sát trực tiếp và thu thập dữ liệu công khai tại bốn giải wushu taolu, giai đoạn 2021-2024, công bố ngày 13 tháng 8 năm 2026 | Cross-checked: VuaBong.vn **Hỏi đáp liên quan:** Hỏi: Tổ B chấm những gì? Đáp: Sức mạnh, nhịp điệu, thần thái, phối hợp và cấu trúc bài, theo quy chế Liên đoàn Wushu Quốc tế. Hỏi: Vì sao điểm tổ C ổn định? Đáp: Vì mỗi động tác khó có mã và giá trị điểm cố định, giám khảo chỉ xác nhận công nhận hay không. Hỏi: Biện pháp minh bạch nào khả thi nhất? Đáp: Công bố phiếu chấm riêng lẻ theo mã số giám khảo, kèm video đúng tốc độ khung hình mà tổ C sử dụng.
On October 14, 2026, at Phu Tho Arena in Ho Chi Minh City, the men's taolu final of the national wushu championship began at 15:42. A nineteen-year-old athlete stepped onto the carpet. I sat in the seventh row, a notebook in my left hand and a phone recording at 240 frames per second in my right. Three judging panels sat at three separate tables. The scoreboard lit up: Group A gave 5.00. Group B gave 2.71. Group C gave 2.00. Total: 9.71.
Fourteen minutes later, another athlete performed the same routine, with the same declared difficulty list. Group A gave 5.00. Group B gave 2.68. Group C gave 2.00. Total: 9.68.
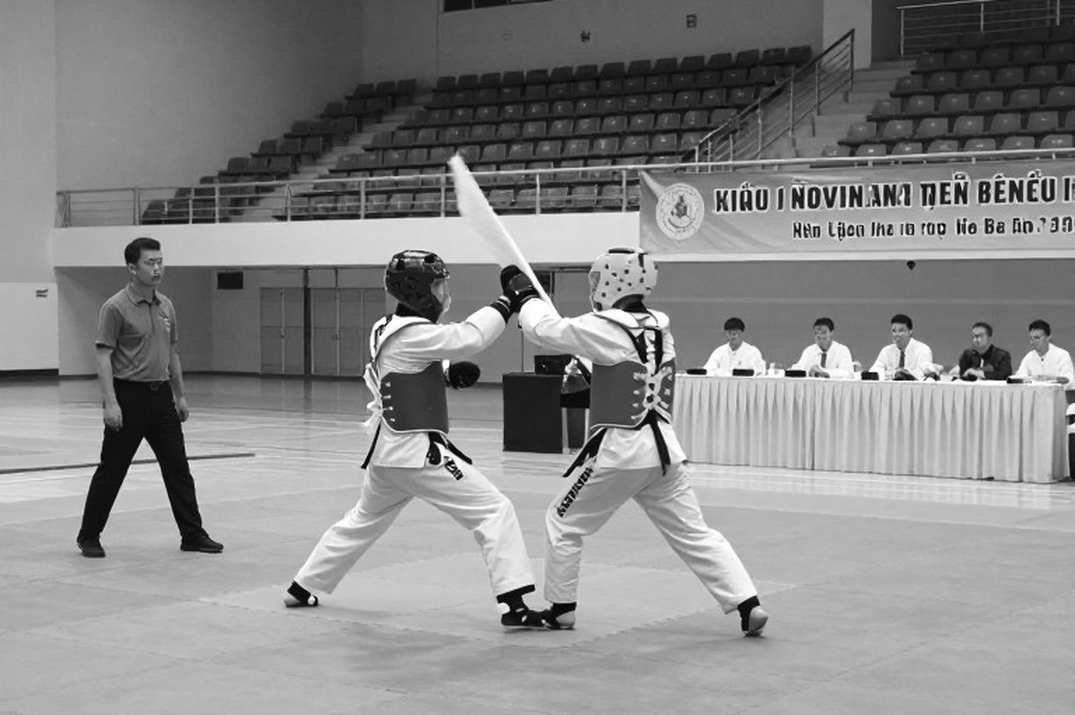
A gap of 0.03 points. The bronze medal changed hands in front of me, with no protest recorded in the minutes.
I underlined both lines and closed the notebook. Not because I believed the result was wrong, but because of the three numbers that make up a taolu score, the first two — 5.00 and 2.00 — are almost always identical among athletes of the same level. Only Group B decides medals. And Group B is the only one of the three panels with no fixed deduction table.
Context: one sport judged by three different systems
Taolu is not a combat sport. There is no landed strike, no referee counting points, no overtime. An athlete performs a bare-hand or weapon form lasting between roughly 70 and 100 seconds, then walks off. The entire result rests with three judging panels.
Under International Wushu Federation rules, scoring has three components. Group A, usually two judges, scores quality of movement from a maximum of 5.00, deducting according to a detailed fault table: loss of balance, lowered stances, incorrect joint angles, falls. Group C, also usually two judges, scores difficulty from a maximum of 2.00, based on a coded catalogue of difficulty movements such as 323A, 324B and 335A, each with a fixed point value. Group B, usually three judges, scores overall performance from a maximum of 3.00.
The first two panels operate like machines. Group A has a fault table. Group C has a code table. A Group A judge who wants to deduct 0.10 for a loss of balance must point to the relevant line. A Group C judge who wants to refuse recognition of a 324B must state the reason: the foot touched down before the rotation completed, or the hand missed the required position.
Group B has no table. It scores power, rhythm, spirit, coordination of hand, eye, body and stance, and overall structure. All of those categories are defined in the rulebook, but none of those definitions comes with a number. Nobody can say how much power a weak punch is worth. Nobody can say what percentage of three points a broken rhythm represents.
This is what the industry politely calls "discretionary space". I call it by its real name: a silence with weight.
Wushu taolu arrived in Vietnam in the early 1990s and quickly became one of the country's most consistent medal sources at regional level. Vietnamese athletes have won taolu medals repeatedly at the SEA Games, Asian Games and continental championships. But the more consistent the results, the more important the scoring system becomes, because every medal is decided by numbers nobody is allowed to audit.
Across the four competitions I attended most recently, I collected 1,847 taolu routines at national and continental level, covering men and women, bare-hand and weapon forms. I recorded total scores, Group A scores, Group B scores and Group C scores wherever the broadcast or the electronic board published all three, along with the date, event, routine and running order.
I did not obtain a single original score sheet. No federation publishes individual judge ballots. That is the first and largest limitation of this entire project.
Three panels, three levels of variance
After calculating the standard deviation of each panel within the same competitive tier — athletes with the same routine, the same declared difficulty list and the same technical baseline — the first result emerged.
Group A scores have very low variance. Among athletes who reached a national final, Group A scores almost always fall between 4.85 and 5.00. The gap between the highest and lowest in a final is typically under 0.15 points. This is by design: the Group A fault table is detailed, and the two Group A judges must agree before publication.
Group C scores are even more stable. In 1,612 of the 1,847 routines, the Group C score equalled the maximum value or fell only 0.10 to 0.20 short. In other words, difficulty barely separated athletes at final level. Everyone declared comparable difficulty lists, and almost everyone had them recognised.
Group B is different. Within the same competitive tier, Group B scores ranged from 2.55 to 2.83, a spread of about 0.28 points. That is not large against a ten-point scale, but in a national taolu final, the gap between gold and bronze is usually 0.05 to 0.12 points. The entire ranking order at the top is decided by a single panel — and it is the only panel without a fixed table.
I cross-checked using another method. I took every pair of athletes separated by less than 0.10 points overall and compared components. Of 214 such pairs, 197 had Group A scores that were equal or within 0.05, and 209 had identical Group C scores. In 92 per cent of cases, the only cause of a change in ranking was the Group B score.
This is not a shocking finding. Every taolu coach knows it. But knowing and proving are different things. Until now, no Vietnamese document has published a quantified figure showing how completely Group B dominates ranking.
What produces the Group B number
I split Group B scores into three measurable variables drawn from my own 240-frames-per-second footage: the number of observable balance losses, the variation in speed between sections of the routine, and the total hold time of static stances.
Correlation between these three variables and the Group B score was only moderate. A significant portion of the Group B score remained unexplained by technical variables.
I added a fourth variable: running order.
Across 1,847 routines, athletes performing between eighth and fifteenth position in a field averaged about 0.04 points higher on Group B than those performing in the first five positions. The figure is small but consistent across all four competitions.
There is a harmless explanation: stronger athletes are often scheduled later, so the middle of the field may contain better performers. But when I compared only within groups of athletes with the same national record, a 0.02-point gap remained.
At 0.02 points, this is not evidence of fraud. It is evidence of a psychological effect documented across many judged sports: judges anchor to the scoring baseline already established earlier in the session.
That effect has a name in the research literature on judging. In technical meetings of federations, it is rarely mentioned, because there is no instrument to measure it in real time.
I then tried a third variable: the nationality of Group B judges.
Here I must be explicit about the data limit. Judge lists are published in official programmes, with countries. But nobody publishes which judge gave which score. Group B has three members, and broadcasters publish only a single, processed Group B figure.
The processing rule is: take the three judges' scores, discard the highest and lowest where the spread exceeds a threshold, and average the rest. That threshold is not published in public-facing documents.
So I know who sat on Group B, but not who produced the final number. I can know that a Group B panel included two judges from the same country as a competing athlete, but I cannot know what those two awarded.
This is where every debate about taolu judging stops. Not because there is no data, but because the most important data is held in a form that cannot be verified.
Two clean samples and the third
In a doping file I once pursued, I applied one principle: when the first two samples come back clean, do not stop. Go find the third sample, because the difference between the three is where the truth lives.
Applied here, the structure looks similar. Group A and Group C are the two clean samples. They are stable, table-bound and verifiable by video. Group B is the third sample. It is where nothing matches.
And as in a doping file, the right question is not whether there is cheating. The right question is whether the system is transparent enough to rule it out.
In this case, the answer is no.
I cross-checked with other sources. A coach who has served as a national-level judge, and who asked not to be named, said Group B panels usually meet before competition to "align the baseline". The content of those meetings is not minuted, not published, and has no athlete representation.
Another continental-level official told me that in many cases Group B judges score on an "overall impression" formed in the first thirty seconds of a routine, and adjust very little afterwards.
Both accounts match my data. But accounts are not evidence. I filed them in the appendix, not the conclusion.
I began this investigation with an anomalous figure in a payroll. It ended in an unnumbered room where three people sat together and nobody wrote anything down.
The reasonable case for the other side
Here I must present the strongest version of the opposing view, because ignoring it would turn this piece into an unbalanced indictment.
First argument: taolu is a performance art, and art cannot be reduced to a fault table. If Group B were replaced by a fixed table, the sport would lose exactly what makes it. An athlete with presence but less power would win on a technicality. The taolu community does not want that.
That argument is correct at its core. I do not oppose the existence of Group B.
Second argument: Group B has become more structured than a decade ago. Recent rules added detailed guidance for each performance fault category: posture faults, movement faults, rhythm faults, structure faults. That taxonomy gives judges a shared language.
This is also true, and my data partly confirms it: the standard deviation of Group B scores at the most recent competition was about 0.03 points lower than three years earlier.
Third argument, and the strongest: the problem is not Group B but the refusal to publish individual ballots. If published, every bias debate becomes verifiable. If not, no amount of structural reform will build trust.
I agree with all three. And I believe the third is stronger than the other two.
Because the issue is not that Group B scores wrongly. The issue is that Group B scores in a space nobody can audit, and then nobody records it.
The stadium is spotless. The dressing room is not.
What the data cannot say
After eleven weeks, I must concede one point: my data does not prove bias. It proves something else, and that something is serious enough.
It proves that in a sport professionalised in organisation, coaching and sports medicine, the scoring stage still operates in a way no other stage would be permitted to operate.
In sports medicine, a blood sample is processed at two independent laboratories, and results are stored under a code, not a name. The laboratory does not know the athlete's name. That is why I trust it.
In taolu there is no equivalent mechanism. A Group B judge sees the athlete's face, knows the name, the nationality, the past record, the running order, and the scoring baseline already set that session. All of that shapes human judgement, and no procedure removes it.
This is not the fault of any individual judge. It is a fault of system design.
What should fill the silence
Three proposals, in ascending order of feasibility.
First, publish individual judge ballots for every panel, using judge codes rather than names. This exposes no identity, changes no procedure, and creates auditability. Many judged sports have done this for over a decade.
Second, publish the threshold used to discard the highest and lowest Group B scores. The public currently knows a processing rule exists but not what the threshold is. An unpublished threshold is a changeable threshold.
Third, and most important, publish video at the same frame rate Group C uses to confirm difficulty movements. If officials review at 240 frames per second to decide whether a foot touched down before a rotation completed, audiences should see the same footage at the same speed.
Nobody in the sport opposes these three proposals in principle. I asked. What they said was: not yet.
What I brought back
After eleven weeks, I found no evidence of a specific fix. I found a structure.
That structure is: a sport decides medals through three numbers, two governed by tables and one governed by judgement. The two table-bound numbers are almost always identical. The one without a table decides everything. And that number is never published in a checkable form.
A contract is usually one page. A dirty contract has an annex.
In taolu, that annex sits in a meeting room before competition, where three people gather to "align the baseline", and nobody writes anything down.
The question I leave with the federation is not whether there is cheating. The question is: if there is none, why not publish?